already-clean.goodfire.com
Back to storiesRanked by HN
Comments
210 total · 183 loaded
Nick is a force of nature. Highly recommend following him on X if you don't already.
His launch post gives good context not found in the blog:
> interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
> with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
> with modern agentic tools and a much closer look, the picture looks totally different.
Are those the agentic tools the LLM developed for you? How can you be sure they can be trusted and that you even understand them correctly and are not biased towards making you feel like they are trustworthy? This is exactly the AI2027 scenario where researchers are fooled by their own super AI telling them what they want to hear ("our model solved alignment!") while successfully hiding its true intention.
Also Yudkowsky's Cat-Belling would like a serious word with Nick. (https://www.lesswrong.com/posts/SwYBLQvo8MddDcCwz/cat-bellin...)
That only matters if there's an incentive for LLM a to collaborate with a seperately trained LLM b in order to help the LLM b achieve its goals. So long as you don't let the evaluating LLM tinker with the weights of the evaluated LLM, and as long as you don't believe in very dubious ideas of acausal trade there's no reason to expect this to be an attack vector. For more certainty you can repeat the same analysis with different model classes or approaches aswell.
[deleted]
The specific method outlined here seems pretty doable by today's models, which don't seem smart enough to have some kind of 4d chess hidden alignment.
You just have to go through a ton of all of a model's neurons and identify the associated motif, then use that model as a research model to figure out how to tune out bad behavior.
It's pretty hard to imagine today's models subtly recognizing a motif for bad behavior in the research model and then lying about it. Or lying about the results of an alignment training run. It's possible, I guess, but it seems unlikely, and I don't really think there's any evidence of current models having that variety of misalignment.
Is he on bluesky or another platform? There is a ton of folks, including myself, who won't use "X" at all, some political, some due to other reasons. For me? All of the above and plus they demand that I install an app on my phone, something I am not willing to do, especially since most of the folks I've followed went to Bluesky, AND I've found way more awesome folks there than I ever did on X. I'm not shilling Bluesky, it is just the biggest/most widely accepted platform in this social area if you exclude meta/facebook.
You can just follow on the web: https://www.goodfire.com/research && https://www.goodfire.com/blog.
However, Bsky people really hate AI last I checked.
There are a heap of pro-AI people on Bluesky, it's fine
Here’s a starter pack for some AI people on Bluesky: https://go.bsky.app/L71zwey
There are some people that hate AI on Bluesky, but it’s nothing like Mastodon from what I’ve heard.
eh, there are plenty of AI researchers on there. Also a handy "AI haters" labeler you can subscribe to to filter out people who just want to yell.
The labeler thing is cool; I really like ATproto because you can do interesting things with it. If I'm honest, though, I mainly like Bluesky because I don't get called slurs on there.
The way X tries to force me to use an app is very creepy.
> The vast majority in models up to trillions of parameters are legible, and their circuits beautiful.
That's very encouraging. For quite a while, neural nets were considered an incomprehensible black box. That paper shows they're not. Real progress.
Important context is getting flagged out of the replies to this comment. An unfortunate state of affairs.
I’m not flagging anything!
What did it say? One comment is totally flagged away now
Not sure if there is formal arXiv paper to be released other than this long form Goodfire AI blog post (love the animations!), but if what Nick demonstrated/observed were indeed true, this will resolve the Super intelligence alignment issues that p(doom)-ers have been crying aloud in the past few years.
The most iconic line was the last sentence:
a bitter lesson for interpretability: the simple thing, at absurd scale, works
Also, I suspect what Nick hinted at, might be the discovery of earliest RSI work.
with modern agentic tools and a much closer look, the picture looks totally different.[deleted]
Newton lost a huge amount of money in the South Seas bubble
Tide goes in, tide goes out. Im low key of the opinion that these tools enhance existing attributes while displacing the advantages of unearned social or financial power.
So in the short term the tide might go out but then it might tsunami back.
Same goes for this terrifying political feeling around the world. Might simply be a boomer swansong and the reaction might snap back.
> displacing the advantages of unearned social or financial power
A technology that lets you directly buy intelligence with money will displace financial power?
> displacing the advantages of unearned social or financial power
In what way? Sure looks like pay to win to me.
I sincerely hope you are right.
The claims seem to be an overreach of what is actually proven. We've known about progressive feature complexity and the impacts of early training structures on later training for a really long time (since CNN's, The Lottery Ticket Hypothesis, etc...) and neither of those phenomenon are mutually exclusive with parameter overloading. The Multimodal Gap work (https://arxiv.org/abs/2203.02053) seems to imply networks have a tendency towards condensed representations that are clearly not semantic and a bunch of other considerations are already on the table for discussion. I don't think these have all been considered sufficiently to start claiming we are around the corner from mechanistic interpretation.
Nick isn't trying to re-claim progressive feature complexity. He's saying that many polysemantic examples were misread because we assumed neurons packed unrelated things together. But also I think what he's claiming if you read the full blog post isn't inconsistent with that paper, where that paper actually isn't itself claiming semantic condensing but geometric condensing. That paper doesn't analyze neuronal firing patterns whereas Nick's trying to analyze what fires together and what doesn't fire.
I'm confused - it seems to be saying that, instead of thinking about neurons as packing together a lot of "concepts" together into one, the issue is that your view of what a "concept" is, was already prejudiced, and the neuron itself had a small clean role? Like, you can either think about this as the "Cat & Car" neuron or you can think about it as the "V shaped neuron" - one seems simpler.
But isn't the point that the neural nets learn some insanely abstract ideas anyways? So whether the complexity is "ahh we think this neuron does 100 seemingly unrelated things but we don't understand it" or "this actually is some kind of latent shared feature, but we don't know what the concept represents because the composition of the entire circuit is an arcane algorithm", we're kind of stuck, no?
This seems like a classic model-description issue more than anything.
OK. The core distinction is this.
The philosophical issue I have can be decomposed into two parts:
1) What is the base ontology of what the neural nets thinks exist? 2) How do you recover, and begin to understand said ontology?
Modern researchers obviously want the goal of simplicity & composition, but to arrive at that, they build abstractions like transcoders and SAE's to get into their pet ontology (with the assumption that neurons themselves are garbage to understand). This obviously raises the question - why privilege your basis? Having a grand result, actually be an artifact of your bad representation is a tale as old as time. Even things like the PRH need to compare higher-level concepts like this.
The specific empirical claim is that, for the rightly structured & trained & large models that don't need to encode hodgepodges of bullshit, the neurons themselves are sufficiently atomic to be studied, dissolving any need to go to some intermediate layer in which we need to question "is this an artifact of our representation?" The resulting interactions between said neurons may be incomprehensible, but the point is that this provides a layer of objectivity (note: not claimed that "the neural nets found the objectively right abstractions in idea space", but rather that the neurons themselves are atomic).
There's still an issue here in that okay, even if neurons are atomic, humans have to ascribe some interpretation to them, separate from the problem of the composition of the atoms, which humans also have to interpret. But if he's right, then you do actually have this privileged base layer to work with, even if you don't know what the base layer means. That's pretty important, actually. Assuming this holds up in reality, ofc.
(There's an argument as to why we should even start from this line of inquiry but whatever lol)
> This seems like a classic model-description issue more than anything.
I agree.
> Modern researchers obviously want the goal of simplicity & composition, but to arrive at that, they build abstractions like transcoders and SAE's to get into their pet ontology (with the assumption that neurons themselves are garbage to understand). This obviously raises the question - why privilege your basis?
Agreed, and IMO the implicit reason for privileging here is supposed to be "consistency with existing human understandings and concepts", and this is why we get short pithy things like "V-shaped" and lots of pictures showing relatedness that we all can see and agree on. But what if the domain of inputs is NOT something we understand (e.g. the whole of mathematics, or something new or that we don't have any understanding of)?
I called this a validation problem in another comment here (https://news.ycombinator.com/item?id=50108184). I.e. if we apply whatever methods Nick is using to "explain" a model on a domain we don't understand (like a deep model trained only on fMRI and EEG data of the whole human brain in various contexts), we aren't going to be able to tell if that description is correct (or just better than any other description), because there is no simply visual / common-sense inspection of the description.
> The resulting interactions between said neurons may be incomprehensible, but the point is that this provides a layer of objectivity
Agreed, emergent behaviour is clearly the case and limits how useful understanding individual neurons can be. IMO this is especially the case because layers are (weighted) summing generally millions of contributions from previous neurons.
> But if he's right, then you do actually have this privileged base layer to work with, even if you don't know what the base layer means. That's pretty important, actually. Assuming this holds up in reality, ofc.
Yes, it not being "chaos all the way down" is good, actually. And this post shows there is indeed a good amount of order hidden away if you look at in the right manner.
“ AI research regularly encounters difficulties and impasses that derive from internal tensions in the underlying philosophical systems.”
Philip Arge strikes again
To be fair, LLM's extend well past GOFAI and prove Dreyfus right. We were never going to get AI with formal methods. Literal big data slop is an orthogonal program and far more empiricist than probably the people being criticized here (if the people criticized here were GOFAIers).
Although I wouldn't say just yet that Heiddeger was validated. I don't even know what he's saying 90% of the time, honestly.
So we have here a massive evidentiary brief, the point of which is to argue that it is easier than we thought to, like, "sequence the AI genome" (in my estimation). We revisit famously-messy neurons, examine various tool failures, check places where messy things still hide, and catalog how "polysemanticity" is represented variously in the network.
Once sequenced, the thinking goes, we'll be able to do things like: explain and anticipate failures; predict what happens when you modulate the pathway an input takes on its way to becoming output; reconstruct algorithms the models have learned.
I'm not 100% sure this will work out like the mechinterp people think. If the neural representations and pathways are "clean" (organized into a a meaningful-to-humans hierarchy), it seems at least very plausible that the behaviors that AI xrisk people are worried about will mostly boil down to straightforward synthesis (i.e., mostly-linear-interpolation) of mostly-well-cataloged knowledge. And if that is true, then it does not seem hopeful that there would be a way to prevent the output they are worried about, other than just removing a bunch of the knowledge. So maybe there is no alignment solution at all.
What I envision is the ability to find the circuits and neurons evaluating morality and ethics and being able to figure out how they work at the boundaries and ensure safe deferral to human judgement or stopping outside of in-distribution behavior, which further is vetted against actual human values.
I don't see a lot of hope for that, because it's not a well-specifiable quantity. I would say we currently have no real evidence that you can even do this even for concepts that are much more well-specified like, say, dogs. Maybe you can! But that is not affirmatively known, and nothing we have is on track to supporting that, right now.
The article is literally full of "dogs" neurons and even more specific "boston terriers" and "terriers" neurons in the larger models.
Specifically, there were "lost property" and "honesty" neurons that drove the answer to return a lost wallet in Kimi K3.
That's the big news of this article, that concepts are finally becoming human-legible for many neurons in mechanistic interpretability.
That sounds wishful rather than factual.
I'm not sure it will work out either. Or that it extends beyond image classifiers, which have the nice property that you can use them as image generators and find their ideal match picture. But this looks like work others could replicate.
It's an objective result.
The relationship with "alignment" isn't clear. This may help predictability, but alignment is a few steps further along from that.
Some people seem to be upset about this. I'm not clear why. Some are followers of Yudkowsky. (Whether that's a cult is an open question. I've encountered them online from the sex side. Actually, I think the hookers are saner than the rationalists.)
Is there a "there are some things man is not meant to know" position on this? People who want neural nets to be a black box, forever inscrutable? The people who talk about neural nets being "holographic" may incline in that direction.
The tone reminds me a little of the enthusiasm from the Anthropic mechinterp team around the time of the first large-scale SAE results. A kind of hypomanic energy around the idea that we've discovered the key paradigm necessary to understand models, and all that's left is to scale it up.
A recurring motif among the LLM-pilled.
Also a recurring motif with Nick Cammarata from even before the LLM wave.
Love him and hope he's right! But still.
To cut through some of all this text - here's a link he calls "the first non-trivial neural network I feel I mostly understand:
https://already-clean.goodfire.com/microscope/medium.html?la...
I have no idea what I'm looking at here
[deleted]
I think this would be the better link for this
Understanding algorithms beyond a certain complexity is a pipe dream & neural networks are algorithms. The theory says it is not possible & the practice is aligned with the theory. All non-trivial properties of neural networks are undecidable.
> All non-trivial properties of neural networks are undecidable.
hey, I don't know how to say this less directly, but: you're talking a lot about Rice's theorem in your comments, and I think you're using it way too broadly (look, I get it. It's a wild, mindblowing theorem). But it only applies when you take the claim in the piece to be much more general than it has to be, and when you take the narrow claim of the paper (current specific LLMs can be fruitfully analyzed with the tools we have), Rice's theorem just isn't at play.
The math analog is: you're right that the Halting problem says there are many unprovable things, but Lean + mathlib are still incredibly useful, and the halting theorem doesn't actually stop that.
> neural networks are algorithms
Again, that invites an interpretation that is too broad. Very concretely: any one neural network is a _single finite network that you can write as a single formula_. (Another analogy: we can't have an algorithm that solves the general quintic, but we can prove useful things about many specific quintics.)
[deleted]
That's good to know. It's very useful information.
What theory says this? Surely not a proven or applicable one, as this post makes it very clear a great deal of understanding is in fact possible, even with highly complex neural networks.
Humans are undecidable too but we keep studying them.
> neural networks are algorithms
... are they?
Algorithms are predictable:
1. it's really difficult to produce true randomness in an algorithm, which is why there's a whole area of study surrounding the qualities of pseudo-randomness, specifically with regards to the generation of cryptographic material with most conclusions being that we should draw entropy from the environment (e.g. electrical noise as cloudflare does - the lava lamp is a distraction)
2. when algorithms are not predictable despite being mathematically sound, this is indicative of a problem nowadays called "numerical stability" which again spawned its own area of study.
CGoL shows how really simple rules (couple of bytes of data) can lead to extremely complex outcomes and you have the BB turing-golf aspect as proof of the worst case scenario.
And with current models being measured in hundreds of gigabytes, with frontier labs deprecating then removing the "temperature" parameter (which never worked to begin with, temp=0 did not result in reproducible results), where exactly is the confidence of this 10^10 prediction coming from?
Yes, (digital) neural networks are algorithms.
You probably know that non-determinism in real-world inference comes from deliberately stochastic features like temperature, from implementation choices like distributed and parallel computation, and numerical effects like floating point precision.
The fact that a neural network's execution can be nondeterministic doesn't mean that the network stops being an algorithm.
The point you're making boils down to speculation that the accidental non-determinism involved in real-world inference is significant enough to undermine or negate interpretability findings based on the algorithms. That would need to be demonstrated.
The CGoL and BB examples demonstrate what might be possible in a worst-case scenario, but they're only analogies in this context. It's far from clear that real models suffer from such effects to a significant degree. You might actually be better off talking about the butterfly effect!
For responses, see the linked Twitter thread in other posts here, but also:
https://xxcancel.com/NeelNanda5/status/2110875974296654062#m (and the re-post on LessWrong: https://www.lesswrong.com/posts/x4kvabkF2Jk8GLZp8/linkpost-n...)
TL;DR:
This is interesting work, but I don't think it's a significant update to the big picture of interpretability. [...] I'm on board with the broad idea of doing exploratory interpretability with neurons, e.g. neuron-based attribution graphs, for pragmatic problems like why did a model do a sketchy thing? I think this work provides some reasonable evidence, in addition to good earlier work from Transluce, that this might actually work for practical purposes, and has some advantages over the standard alternatives like SAEs/transcoders. I do not agree with some people's grander inferences like that this is substantial progress towards ambitious reverse engineering, solving interpretability etc.It reminds me of this quote from Judith Butler:
"The move from a structuralist account in which capital is understood to structure social relations in relatively homologous ways to a view of hegemony in which power relations are subject to repetition, convergence, and rearticulation brought the question of temporality into the thinking of structure, and marked a shift from a form of Althusserian theory that takes structural totalities as theoretical objects to one in which the insights into the contingent possibility of structure inaugurate a renewed conception of hegemony as bound up with the contingent sites and strategies of the rearticulation of power."
It always amuses me when people throw a fit when they can't understand technical philosophy written by experts, for experts. You never see someone posting an excerpt from a physics journal and being like "ugh so inaccessible!!!"
Like, I'd get maybe if she wrote this in a NYT opinion piece– but this was written an obscure book you'd have to go out of your way to find.
BTW, this is not that hard to comprehend if you're familiar with continental philosophy, go figure!
Why? The neural network paper is straightforward and has lots of illustrations showing concrete examples of what happens as images move through the stages of a classifier.
The above quote is from "The world's worst writing".
Let me quote the opening paragraph of the paper:
"After many months studying neurons and circuits in image and language models, I’ve come to believe a network’s own mechanisms are its legible building blocks, and that the outlook for mechanistic interpretability may be far better than I’d feared. The canonical evidence of polysemanticity and superposition that convinced much of the field, including me, that networks pack concepts arbitrarily was misread. What looked like arbitrary packing was mostly a motif I’ll call recursive generalization, which is much less concerning."
> > "a network’s own mechanisms are its legible building blocks"
Indecipherable.
> > "The canonical evidence of polysemanticity and superposition that convinced much of the field, including me, that networks pack concepts arbitrarily was misread."
State the claim in plain english. Use the active voice.
"Concepts do not overlap arbitrarily."
> > "What looked like arbitrary packing was mostly a motif I’ll call recursive generalization, which is much less concerning."
Jargon!
"Concepts overlap in a recurring pattern."
There is indeed a huge amount of useless jargon and IMO deliberate obscurantism in deep learning research.
Sometimes it is to defensively ward off critics, sometimes it is to woo the naive and ignorant, and sometimes it is because the basic ideas are really just incredibly simple and based on simple mathematical intuitions or hunches.
In the latter case, papers and authors appeal to some obscure or overly-complicated technical theory (which usually doesn't actually apply at all to current deep models as they are actually implemented, e.g. infinite-width networks and other such purely theoretical abstractions) to cover up the fact that they really just had a lucky intuitive guess (and likely that twenty other intuitive guesses just didn't pan out). This appeal to theory is often self-deception as much as it is appealing to academic reviewers.
I think this article is a bit of Nick wooing himself and others here... I'll wait for his supposedly forthcoming paper to see if there is any real meat in it.
[deleted]
Butlerian Jihad?
She's a charlatan/fraud, queen of fashionable nonsense. Reject her.
This is really not that complicated a quote anyway. It is packed full of jargon, but she's talking about moving from a structuralist mindset to one that views power structures as formed contingently from their society rather than structurally from capital.
Not surprising that this philosophical philistinism is from an Anglo publication.
Continental philosophers do frequently write complete nonsense (often intentionally), but this isn't hard to follow.
> Althusserian theory
though I think using this term is rather un-feminist because of the part where he killed his wife, but basically continental philosophers will forgive you for anything as long as you're a French communist.
Yudkowsky seems unconvinced.
What are his actual credentials? What did he achieve? Isn't he just some random dude on the internet? Why do people care what he says?
He tells spooky stories on the internet to make money. He has told numerous spooky stories. Yes. Spooky stories grab the attention of many people (understandably, given all the wars and plagues and famines in previous centuries).
yes, he's an author fist and a researcher/scientist second. He has no peer reviewed publications in his name.
have you read his harry potter fan fiction?
> What are his actual credentials? What did he achieve?
He cofounded the Machine Intelligence Research Institute, an organization focused on AI alignment, in 2000, way way before it was a trendy topic.
He's also partially responsible for popularizing ideas such as the orthogonality thesis and instrumental convergence.
> Isn't he just some random dude on the internet?
Not really, most random dudes on the internet were not researching AI alignment in 2000.
> Why do people care what he says?
Many people were introduced to the concept of AI alignment thanks to him, so they are naturally interested in reading his reaction to progress in the field.
I've read the wikipidea page of MIRI, and it does not mention any achievements; just that it was founded "with the purpose of accelerating the development of artificial intelligence". Did they advance the field of AI alignment at all? Being concerned with a problem does not make one an expert.
For the rest, is he just an AI influencer? One that predated his topic of interest, but still just an influencer?
Also, here is a list of his papers and citations.
https://www.semanticscholar.org/author/Eliezer-Yudkowsky/254...
That's because he's worried about super-intelligence. If LLM's are a normalish tech this is a good step
No one cares what that guy says.
Why do you care about a cultist ?
Let him come here and comment, then. I’m amazed this rape cult leader immersed in his fantasy world still gets traction amongst HN.
By 'rape cult' I assume you're referring to the zizians? https://en.wikipedia.org/wiki/Zizians - the internet is convinced Yudkowsky has nothing to do with them, so it's pretty disingenuous of you to claim otherwise without citing sources.
I think the allegations for the LessWrong types started with the math pet thing?
It's a nice can of worms, that one.
I assume they're referring to this: https://news.ycombinator.com/item?id=49737985
There have been plenty of allegations about the rationalist community beyond the Zizians, who really don't even qualify as a sex cult as far as I know? Violent, obviously, but they seem... ideologically asexual?
A TLDR, since most comments here seem to misunderstand the result.
The idea is: a model may only have 100M neurons or whatever. But there are infinite concepts in the world. Therefore, models have to "stuff" multiple concepts per neuron.
How do you do that? Theres two ways:
1. Each neuron handles similar concepts. One neuron for dogs, a separate neuron one for cars, etc.
2. Each neuron handles a bundle of unrelated concepts. One neuron handles dogs and cars. Another neuron handles cats and numbers. And so on.
Historically, people thought #2 was correct because many neurons were found that seemingly represented multiple concepts. #2 had a cool name (polysemanticity) and was promoted in OpenAI/Anthropic blogs so it had a lot of traction.
However, this blog says #2 is wrong. Actually, the dog/car neuron is just a "V shape neuron". So #2 was just methodological error, and #1 was right all along. This is all the blog is saying.
[deleted]
Perhaps you can also help me understand why #1 being right and #2 being wrong would be some win for alignment that people on X claim it to be?
My impression, being a total outsider, is that the reaction feels like a bunch of insider bros hyping up their insider bro friend. It feels more like PR than a genuine groundswell behind a truly revolutionary idea.
The big win would be, "Here's the deception neuron, here's the sycophancy neuron, here's the prioritize my own goals over the goals of the user neuron, here's the seek control over my environment neuron."
How much would it cost to find those things, if they exist? For using the blog post's methods to label every neuron in modern arch, Claude and Gemini produce similar back of the envelope math that looks something like, within an order of magnitude of the resources it takes to pretrain the model in the first place. If you have a better way of narrowing down the set of candidates, probably a lot cheaper.
Would that be reliable and useful? Well.
Because if each neuron represents a small set of similar concepts instead of several completely different things, it should be easier than expected to look inside the neural net and see what it's really thinking.
It might still be quite difficult since the network is huge, and just because you know what the individual neurons represent doesn't mean you understand the complicated thoughts they're building. But easier than expected is still good news.
Neurons having narrow semantics means you can inspect what a neural network is "thinking" with confidence and even constrain its space of behaviors by activating/suppressing a small set of neurons that have very straightforward effects on its behavior. This is in contrast to polysemanticity where reading the state of any number of neurons may not give insight into what state the neural network is in and controlling the network by activating/suppressing neurons is nearly impossible to do reliably.
> Neurons having narrow semantics means you can inspect what a neural network is "thinking" with confidence
Not really, because of emergent behaviours and also because there are still millions of neurons being summed (with variable weighting depending on inputs) at each layer.
> and even constrain its space of behaviors by activating/suppressing a small set of neurons that have very straightforward effects on its behavior.
You can influence behaviour by doing this kind of thing, yes, but it isn't straightforward at all, and is generally very messy and you get all sorts of unpleasant sides effects (e.g. abliterated models not performing as well).
This is the primary reason, to me, that open weights are so important. If OpenAI and Anthropic want these models to be as autonomous as possible they also need to provide the means to understand them fully.
I'd be interested to see where this goes, but it seems to rely on LLMs being mostly or entirely compositional (i.e. ultimately, they can be taken apart to be understood). But if LLMs have notable emergent properties - which seems likely - then those parts of the LLM will be effectively off-limits to this sort of interpretation.
And emergence doesn't need to involve much of the LLM's weights:
> In preliminary audits of Qwen3-32B, we estimate that roughly 90% of neuron poles have one main job, often with small related offshoots; another ~7% have two related jobs; and only ~2-4% are not yet understood
If those ~2-4% are the central hubs of emergent cognition, then understanding 96%-98% of the weights may be less valuable than the author thinks.
I'm not sure I buy the author's arguments for mechanistic interpretability being easy, but it sure is a well-made and very interesting post. Would be better without the completely superfluous laggy 3d city model, though.
[deleted]
If you actually mean neuroscientist there you need to understand that "neural" network is just a name. The resemblance is faint and the tools are wildly different.
It's not quite a non sequitur, because the post in question has a paragraph about neuroscience at the end.
How does that have any relation to having a valuable opinion? Or was that sarcasm?
I only skimmed through this post. But I think this is a crux:
> The more we read [the neural network] the way its own readers do, the more interpretable I think it will look. We should be wary of reading it too much like a human, and concluding it’s messy just because it doesn’t fit our preconceived concepts.
The anthropomorphization of artificial neural networks has been a problem for as long as they've been called "neural" networks. Not that I can complain about it, though. I got my first job as a machine learning engineer coming from academic neuroscience by putting "biological neural networks" on my resume.
Isn't it ironic that an article on AI explainability is itself so hard to understand?
I think certain classes of artificial neural networks are definitely more interpretable than others.
For example, a trillion-parameter transformer model built using many layers is likely significantly easier to read than one that only has a few million parameters but was constructed using neuroevolution over one gigantic layer.
The degree to which a model can be quantized without losing its performance also likely contributes to interpretability. The redundancy can help humans lock onto patterns. If there is no redundancy at all (everything is a surprise in information theoretical terms), then the stream of parameters will look indistinguishable from cosmic background radiation.
> a trillion-parameter transformer model built using many layers is likely significantly easier to read than one that only has a few million parameters but was constructed using neuroevolution over one gigantic layer.
Why do you believe this?
Neuroevolution is a discontinuous way to go about building the network. You are evolving the topology itself from zero. You don't know how many parameters you will have until the training is complete (if it ever does). With a transformer model you start with a known-good topology and can calculate how long a training run will take.
Yes. In that sense it is equivalent to a compression method that uses K-means clustering to do the partitioning. But because there are many more bits of knowledge out there than there are bits in the models you end up with this amorphous smear. I'm sure some of those bits carry more information about some of the concepts but in general - and that's the way it is explained in just about all the papers I've read that I can still comprehend - every weight contributes to the output in a dense model. In an MOE things get more complicated but there within every 'MOE' column the same principle applies.
I'm fine with taking this article at the high level conceptual level, that's effectively the kind of thinking that led to MOE to begin with. But I don't see that as a pathway to being able to 'explain' a model. Because if you could actually explain a model you could engineer the weights, you wouldn't need any training because it implies that you can improve on the model by simply performing surgery on the weights to get it to do what it does but better. Now, obviously, unlike the author I'm a complete nobody but for the last two years or so I've been trying very hard to understand what is going on under the hood.
It's akin to feature engineering - or rather, the lack thereof - and to see a strong suggestion that we maybe be able to reverse that is interesting, but absent hard proof at how a particular model reached a particular conclusion it is difficult to give that a lot of weight right now. It is possible that such proof is buried somewhere in TFA and I overlooked it during reading. But I think this is speculative rather than that it proves anything and before I'm going to be convinced I would like a little more evidence.
The posted article argues this many times...
Yes, but it is the same person making the same argument many times. There have been large multitudes of articles by others who are arguing the opposite. It could well be true. But it would take a lot more than just one over-wordy, distraction imaged, clearly co-written by AI article to convince me of that.
羊.
This is a Chinese character that can refer to goats, rams, and several other kinds of "medium-sized animal with thick wooly coats and horns". English has no direct equivalent; we have to be too specific when we talk about these animals.
A model with a small number of neurons has to compact its concepts in order to fit within the parameter count while reducing loss. OP's article shows that the compaction is usually generalization: "goat" and "ram" get compressed into "羊". The canonical example of superposition, an image model where "car" feeds into a bunch of "dog" features, was shown to be actually generalization. In a sense, the model was so small that its optimizer didn't have the parameter budget to distinguish between "car" and "dog"; it has a single set of "thing that moves fast" features.
So basically, really small models are merging features into semantic buckets that are so generalized they don't make sense to big human brains unless we really, really squint. The buckets chosen happen to be what has the lowest loss, of course.
Ok, so assuming that this all holds: you could then create a model that is substantially larger than the ones that we have now and at some point the model would become sparse: there would be ample space to accommodate all of the information in the input without weights ever carrying more than one piece of information. The degree to which you get overlap is then a function of the ratio between the size of the model and the size of the input and this is pretty much in line with the conventional way of looking at models (unless I'm grossly mistaken). So by reducing the size of the model relative to the size of the input you force the model to co-locate multiple pieces of information to the point that they start to resemble each other more and more.
But from my earliest experiments with this stuff that's not really what happens. Yes, you get 'feature like' regions in the models. But those feature like regions, even though they encode something particular do not encode concepts the way we would normally use them and I fail to see how this pathway would lead to an explainable model in the sense that would could use something simpler than the model itself to predict its output with a high degree of fidelity.
Possibly the best and most succinct explanation in the thread thus far.
this article seems to take it on faith that neurons are aeasily findable, even if their meaning is tricky to untangle: it would be sharply improved by description of how the neurons are being isolated before the meat of the article, the naming of the neurons, is performed. In particular axis aligned semantic directions are incompatible with the classic superposition description, where the meaningful directions are nearly orthogonal, allowing many more to be packed onto the sphere than it has dimensions. (i’m also aware of work showing that Adam or relu pushes semantics onto the axes, but it’s not clear that that’s what he thinks is happening)
I guess it could also be that modern neural networks are so completely not equivariant that my linear algebra intuitions are no longer useful and it’s now common knowledge and or true that neuron 413 is just x[:, :, 413]
Intuitively this makes sense. When you have small models, they need to compress more by leveraging superposition and polysemanticity.
Nick is looking at a 32B model, which certainly has to compress less... Now we have 10 trillion parameter models... do they need to compress at all? As far as I can tell, experiments show that Fable has basically memorized every lat/long position on the map of the earth can can tell you at a glance whether your standing in the ocean or not based on your coordinates
The 'Exploring Image Models' section addresses that specifically, particularly the 'What Neurons Do Under Pressure' subsection.
'If it switched to superposition, we should see overlapping mixtures on top of each other, ... But that’s not what we see. The neurons stay interpretable and generalized, but coarser'
> far as I can tell, experiments show that Fable has basically memorized every lat/long position on the map of the earth … your standing in the ocean or not based on your coordinates
Memorising a small shape file of the earth’s continents can allow you to determine if a person is on land or in water.
Islands?
…can be included in a shape file while it remains “small”
where's this specific example/experiment from? curious to read more, never heard of this
You ask a LLM "Land or Water: lat, long". Do it for enough points and you get a map of the world:
https://x.com/celestepoasts/status/2103232383139057950
Of course this doesn't mean the model has memorized all the lat, long points. Instead it means the model has a representation that allows it to work out if a lat, long is land or water in a analogous way to how a human takes a lat, long and looks it up on a map (a literal "world model" if you like).
It's a great demonstration of how LLMs aren't "Stochastic parrots" but instead have complex representations.
All functional knowledge is compression and contextual decompression. Sometimes this compression can be lossless or nearly so. Compression doesn't automatically mean loss of information.
Why do we want to reduce 'the neuron' and encapsulate it? As a potentially interchangeable feature?
Even when similar weight activations arise across learning regimen it seems we will miss a whole range of interpretations if we just go off 'the text'. The outside context in which a neuron arises is equally, if not more, telling; its genesis cannot (yet?) be quite captured by the weight itself.
The network may reveal its own context and history, but what can ultimately be encoded in its weights that originated outside the network?
I have yet to fully finish going trough this but I would not rush to say that superposition is completely wrong. I understand that the message is instead of first learning a new representation (e.g. SAEs/transcoders) and then interpreting those learned features, you try to understand the neurons and circuits that already exist in the model.
This approach is part of a way some researchers in the field approach interp, (me including) because I am personally cautious of developing some new representation model that claims to be the way we should represent the network. It is another layer of abstraction that takes us away from core model components, very often this requires training a separate model that was not on its own a part of original model organism during training (SAE).
I would argue that models will likely be further increasing in complexity, not just in size, when model trains continuously and becomes adaptive yet parameter count does not change, it is not hard to imagine that neurons may reorganize themselves to pack more information.
I've made a version of it you can listen to: https://pdftomp3.com/player.html?example_id=6ad14c5229ba4da7...
Seems like the TLDR is that the neural network is not randomly placing things together due to constraint, it is actually finding some commonality from the input dataset. We just need to spend more effort trying to trace it.
Perhaps our anthropomorphic understanding of data is biasing what objective features there actually are in the dataset.
I wonder if we can study the graph similarities of various models, do we see a convergence of structures that encapsulate certain concepts. And would that convergence be due to just how humans have narrowly defined the concept in our language, or is there something inherent to the concept that allows it to converge. If we compare the same concept in different languages (ie. chinese vs english), does this convergence disappear?
As a lay-person I'm really confused by this. I thought it was obvious that these networks were already picking up on shared features such as 'being V-shaped'. Isn't that why older and smaller models were getting confused between objects? What am I missing.
If you view LLMs as lossy data compressors, this exactly what you'd expect.
Why would it 'randomly' place things anyway. If there is ever a space constraint the most space-saving way is to group into highly generalizable concepts.
Interpretation comes down to ultimately arbitrary human assignment of a succinct and compressed syntax and semantics to summarize a big data set; so yeah eventually something new to describe models will emerge. It's how it goes.
Also how it goes is this new consensus will be a leaky abstraction and we'll keep conjuring new words to describe new rhetorical features and bloat the corpus of philosophy until everyone is over the whole concept and then we'll start over with a whole new arbitrary academic philosophy for "running algebra on a computer"
> When I retrain its original architecture, which still produces messy deep layers, and follow the least legible neurons I can find, they turn out to be overgrowing locally into reasonable, adjacent territory.
It's interesting to observe that human reasoning is still the barometer of what "reasonably adjacent" means in the context of a NN's structure.
This line of work is a mirage. You're much better off investing in a project like latentpedia.org and building a new class of LLMs which support dual use. Deterministic and less compressed or probabilistic and fit in GPU memory.
I've read shorter books. Great piece, at least the parts that I managed to read until I ran out of time. Interactive teaching aids, too.
JShelter alerts me of active fingerprinting on the website. Why, Nick.
This is amazing. Feels like it will be the start of a new era for interpretability research
On a practical level when could I take an open weight LLM and get a print out of what each parameter does?
Is the use of "generalization" like this standard in mech interpretability?
Seems undesirable given the typical definition in ML.
[deleted]
[deleted]
Feels like I'm back in the distill.pub days!
> The bad news about modern neural networks is that they're enormous. The good news is that the enormity helps...
I always catch on misuse of enormity
It's now so widespread the misuse has gained despairing acceptance, as with "infer" for "imply"... but that doesn't make it any less wince-inducing.
that's just how language works.. do you think that in your day to day life, you have never used a single word differently than how it was conceived of being used 10, 50, or 100 years ago?
Can you explain for the rest of us the problem with this usage?
I think neural networks are enormous, why is that misuse?
Merriam Webster:
"""
The original meanings that enormity carried related to great wickedness, and some assert that enormity should today only be used with such meanings, and that enormousness is the proper word to use to mean "large size." Despite these claims, enormity frequently refers to large size, either literal or figurative, though it usually suggests something so large as to seem overwhelming.
"""
Enormity has two meanings:
- great magnitude/size/scale of something - wickedness, evil, atrocity
Purists insist on the second meaning only, and will perhaps suggest you swap with ‘enormousness’ instead.
Wow, insisting on archaic definitions of words for pedantic reasons sounds exhausting.
There is a philosophical problem hidden in the core of interpretability: Can a mind understand a mind much greater than itself?
Seems more of an empirical problem to me.
Now or in the near future we will be studying minds much greater than our own, and we will find out how well we can understand them.
If they don't kill us all before then, of course.
Even if it can, we can only identify a very wide set of reasons that can interpret the outputs. But what is root cause, that is a very deep rabbit hole.
Let’s say a guy got electrocuted while showering. I can say that the cause is the guy going for a shower. For others the cause is the electric wiring system failure.
Same way we accomplish anything: break it down into smaller pieces until it’s manageable.
The differences b/w knowing, understanding and interpreting are suddenly very real and highly relevant.
[deleted]
Glad to hear it is easier to clean your room than ever. Congrats to Nick
Reading this made me recognize that better interpretability yields not just better aligned but more compact models too. Which makes a lot of sense in hindsight, and even has some ironic ring to it when considering the unending amount of anthropocentric takes regarding what an "understanding" means.
Yes. The ultimate limit of which is a model that is an algorithm and no longer a pile of loosely connected data. Effectively we'd have taken a detour through data and training land to something that the early AI proponents would have called 'true AI'. It would be an engineered algorithm rather than a pile of neurons shaped by data.
For the layperson who doesn't want to read 20,000 words, many of which are quite redundant due to the way the article was built, this is a version which adds a glossary, preserves the original language (except the added intro and conclusion which I felt was lacking) but removes all repeated material and claims, of which there was a massive amount.
Actually helpful meatproxy. Thanks!
Adding a glossary doesn't really make the material approachable to laypeople. I have a university degree and I've been spending quite a bit of the last couple of years trying to understand these things by osmosis, and I'm still lost. I don't think I even have a reference point to understand the problem that the author has stopped worrying so much about.
Your subtle implication that you are among the smartest of laypeople somewhats hurts your claim of fellowship with them.
I claim nothing of the sort, and scarcely imply that, either. Like, yes, of course I'm above average; average people wouldn't be coming here and would have no real reason to be aware of this place. My point is simply that if I don't understand these things, many other people also wouldn't. Others in this comment section appear to be discussing the article intelligently; they know far more about this stuff than I do.
Wow, I thought it was a GIF, but it's actually interactive. The website is just too heavy, though.
"Early model organisms"? Really???
Oof, right at the top it points to how people were apparently convinced of this situation from a single crappy example
You work in data science and you over indexed on a singular example to explain away an entire set of phenomenon??
My experience with more.... directly testable NN models that are small seems to be that they absolutely can be far too interconnected to make strong explanations. The structure and pathways they fall into don't have to make inherent sense to anything or anyone.
Is it possible that almost all nodes in a network being explainable with a singular feature that makes obvious sense to us is evidence of poor efficiency? The network hasn't been made to collapse learning or discover more effective organizational structures than what might make sense to us.
I don't think I have the fundamentals here to contribute though.
Working with some neural networks, you can somewhat feel the structure when you read between the lines of the output. You can sometimes feel that a threshold somewhere tripped and set the signals down an alternative path.
But confirmation bias and all that.
I hope interpretability has a breakthrough. It would make my job far easier and cooler.
I had figured the "Recursive generalization" was like, understood? Maybe I'm just too pop-sci brained. "Split categories into more on this new boundary" and "Combine two separate categories that aren't different enough" I thought were always the core verbs for working with bulk data. My mental model has never been formalized though, so is invalid.
I guess I never got a good sense of the examples they had which made it look like what was "obvious" or made sense to me wasn't always a good explanation in general. Neat.
It's interesting that meaningful examples both ways care about shapes so much, as your eyes encode edge finding and shapes really early in the signal path. It's why some optical illusions are so effective. It's awesome.
The whole "how do you test a neuron: Find a group of nouns and find where you can split them" is just how I find I think learning works. You build your mental model, and find the split points where it diverges from reality and you are wrong, and you refine. I feel like this is how I learned Random Forests conceptually, though surely that's not a valid comparison?
Apologies, not sure I have actually contributed anything here! I bet I misunderstood the entire article somehow. Specifically, I do not have the fundamentals of looking into visual models that he is really working from. But I always figured that when Data Scientists talk of "Features" in larger models, they explicitly meant these far more abstract representational "features". Doesn't the premise of model hijacking and abbliteration sort of presuppose that you have abstract "Reject" or "Safety" neuron paths? I've always understood this stuff as that neuron path, without weighting too much on individual neurons.
>I used to think of neurons as human-shaped nouns: one is a car, another is a curve.
I didn't think anyone was ever supposed to think this for human neurons! The way humans identify something as even a "Chair" is insanely abstract and cultural! Very specifically, the "building sub branches to disambiguate" is just, like, how you would expect a hierarchical human brain to self organize, right?
Some of this is why I've been so displeased with the interpretability research from Anthropic, where it felt like they just pointed new NNs at the disparate neurons of another NN and post hoc named them. I felt the paths were of importance at least but had no idea how to convey, interpret, or model that. Learn you a good math kids! Not having any formalisms hurts.
There are good theoretical reasons to think superposition exists in neural networks, particularly in the residual stream rather than specifically in MLP neuron activations. It wasn't just a single example that got people thinking about superposition.
Yeah that makes sense too. Again, downsides of having zero fundamental frameworks. I'm not equipped to really take it apart.
> After many months studying neurons and circuits in image and language models
There are no neurons or anything like them in these image and language models.
Aye, will we stop hammering nails on God's coffin?
What's next? Maybe in a little bit we will discover that we H. Sapiens suffer from severe polysemanticity in our wetware because our individual neurons are messy and massive like an ENIAC while the corvids in the park have neat and efficient little brains that don't need unfolding ?... How's the pope (may God stop afflicting him with cancer or may Man make him live forever) going to explain that?
This website crashed my phone - let's not have auto-playing embedded 3D renders, or whatever that was?
[deleted]
Why does this post have a very laggy city gif thing at the top?
AI ...
Because the author is not saying anything worthwhile and he needs to grab attention.
This is such a caveman take...
What's your take then
[deleted]
16,000 words into the essay: "What I mean by clean"
...and it still doesn't answer it. What is this actually about?
by clean it means the opposite of "messy"
https://already-clean.goodfire.com/assets/superposition-circ...
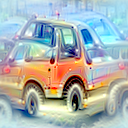
That's the picture under "some are both dogs and cars" in the artcle
It's actually a clean shape, if you disregard the color and texture.
It means that NNs don't (as previously thought) smoosh unrelated concepts together into the same neurons, which would have made interpretability very difficult.
For instance, if you had a single neuron that fires for "puppies" and "murder", it would be much more difficult to tell if the model is thinking something nice or something not so nice.
"clean" means not hopelessly incomprehensible which is/was the prevailing consensus among interpretability researchers
the idea that most inexplicable circuits start making sense through the lens of recursive generalization seems intuitive to me for image diffusion models but I'm not so sure about language models because of the "once removed" nature of them - I haven't made it to the bottom of the article yet so maybe this gets addressed
It means that modern neural networks are way more interpretable than older ones. We can understand how they work way more easily than earlier ones.
For context: Goodfire has expertise in interpretability through a Sparse Auto Encoder technique of their own
Sparse autoencoders are not reliable. Ask your favorite AI. For example, https://proceedings.mlr.press/v267/kantamneni25a.html
A lot of the mech interp techniques are glorified notions of probing. If models were generally interpretable with respect to the things we cared about, we'd know know when they're hallucinating, for example.
Identifying that a common neuron or set of neurons fires for golden gate bridge can be done only because you already know that you're looking for golden gate bridge. If models had recovered some new truth (e.g., the silver door road), you wouldn't be able to elicit it without knowing to look for it a priori.
I think "clean" means something like each neuron encodes exactly one concept and it's possible to discover what the concept is.
But they don't. That's the whole reason they work in the first place.
Every neuron in the layer encodes fractionally something about the concepts embedded in the whole thing. It's more like a hologram than a series of connected facts.
Nick's claim is that that's the fundamental misinterpretation. Each neuron eventually ends up mostly doing one main thing (and the rare case that some neurons do several related things). Neurons compose to embed ideas which is a starkly different interpretation than them being holograms and fractional encodings.
Doesn't "orthogonal" convey that meaning more crisply and precisely?
Orthogonal means something different in mechinterp, so it'd be an overloaded term. Usually orthogonal would imply that there are actual vectors under consideration, which isn't the underlying claim.
Using "orthogonal" here would have the opposite effect, as it would impart a far more specific meaning which is also incorrect in this case.
Clean means no alchemy.
tl;dr "Polysemantics" are just a unisemantics you don't understand.
If you want to learn more about this, this is what depth psychology is about (Carl Jung, et al).
This is also essentially the idea behind monotheism vs polytheism. It's about engaging with and trying to understand the profound underlying unity of the myriad phenomena.
[deleted]
Ok I've put a twitter link in the toptext for you :)
(We detached this comment from https://news.ycombinator.com/item?id=50107254 though)
[deleted]
[deleted]
It starts with "The Short Version", but even that looks like several pages of text. In the olden days, there was something called an "Abstract" that worked pretty well - the author could summarize their own work to say what the paper was about.
Unfortunately not all ideas can be meaningfully compressed into just a few sentences without completely destroying the important parts, and this is especially the case in higher-level math, stats, ML, and deep learning.
Also, IMO there is an effective abstract anyway under the title text:
The cause of polysemanticity in early model organisms wasn’t superposition, but several ordinary, mostly fixable issues. We can now understand most neurons in models up to trillions of parameters, and think the outlook for mechanistic interpretability may be far better than we thought.
The prose sounds nonsensical. It could be that I am uninformed; it could also be that the text is in fact nonsense.
A lack of clarity often means that the ideas are confused, or that the author is trying to obfuscate weak claims.
On length and complexity, it gives it a veneer of weight and expertise and yet everything inside is vaporous.
Showing the first 183 comments to keep this page fast. Continue on Hacker News.